publications
I am primarily interested in policy adaptation using compositional or modular appraches. I believe composing modalities will play an important role in developing generalist robots as paired scaling of all sensory data is difficult, and we will need efficient ways to compose information obtained through different modalities. Prior to joining the PhD program at Arizona State, I worked on NLP research at Wells Fargo.
- NeurIPS 2026 Imitation LearningSelf-Supervised Keyframe Discovery for Horizon-Invariant Behavior CloningTL;DR Learns what a behavior cloning policy should remember: compact, decision-relevant observations discovered from demonstrations and retained across long horizons.In Advances in Neural Information Processing Systems (NeurIPS), 2026
- ICRA 2026 Robotics Systems Imitation LearningPokeNet: Learning Kinematic Models of Articulated Objects from Human ObservationsTL;DR PokeNet is an end-to-end framework that learns articulation models from a single human demonstration without prior object knowledge.IEEE International Conference on Robotics and Automation (ICRA), 2026
- ICRA 2026 Compositional Learning Imitation LearningFactorizing Diffusion Policies for Observation Modality PrioritizationTL;DR A policy formulation that enables observational modalities to have differing influence on the action diffusion process by design.IEEE International Conference on Robotics and Automation (ICRA), 2026
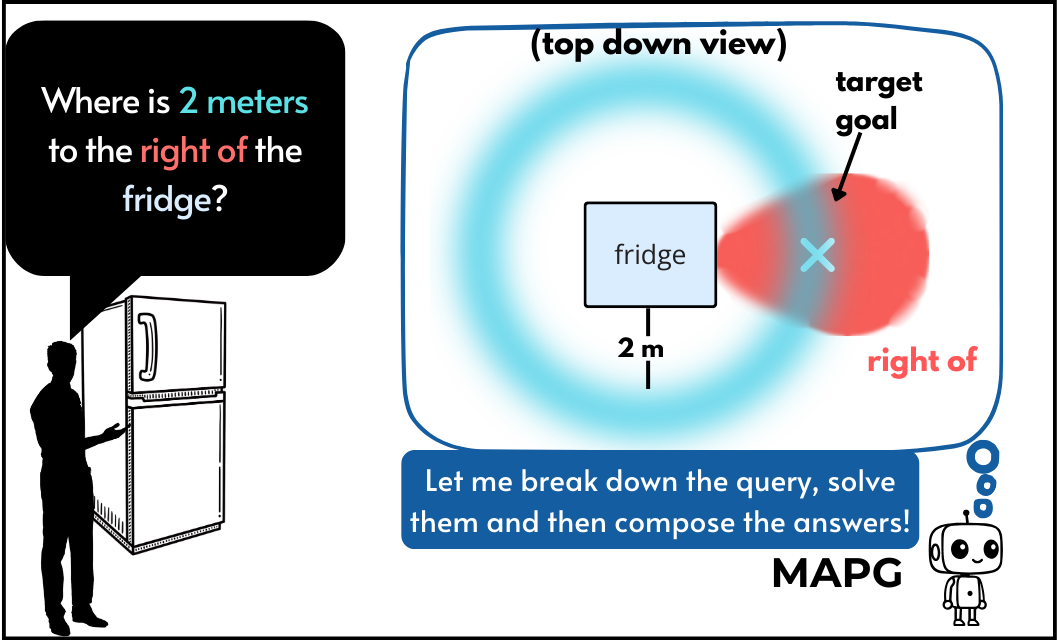
- arXiv 2026 Compositional LearningMeanings and Measurements: Multi-Agent Probabilistic Grounding for Vision-Language NavigationTL;DR MAPG is an agentic framework that decomposes language queries into structured subcomponents and queries a VLM to ground each component.arXiv preprint arXiv:2603.19166, 2026
- arXiv 2026 Policy AdaptationYou’ve Got a Golden Ticket: Improving Generative Robot Policies With A Single Noise VectorTL;DR Swapping the Gaussian initial noise of a pretrained, frozen diffusion or flow matching policy for a well-chosen, constant initial noise input – a golden ticket – improves its performance.arXiv preprint arXiv:2603.15757, 2026
- IROS 2026 Robotics Systems Policy AdaptationStageCraft: Execution Aware Mitigation of Distractor and Obstruction Failures in VLA ModelsTL;DR A training-free approach to improve pretrained VLA policy performance by manipulating the environment’s initial state using VLM-based in-context reasoning.IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS), 2026
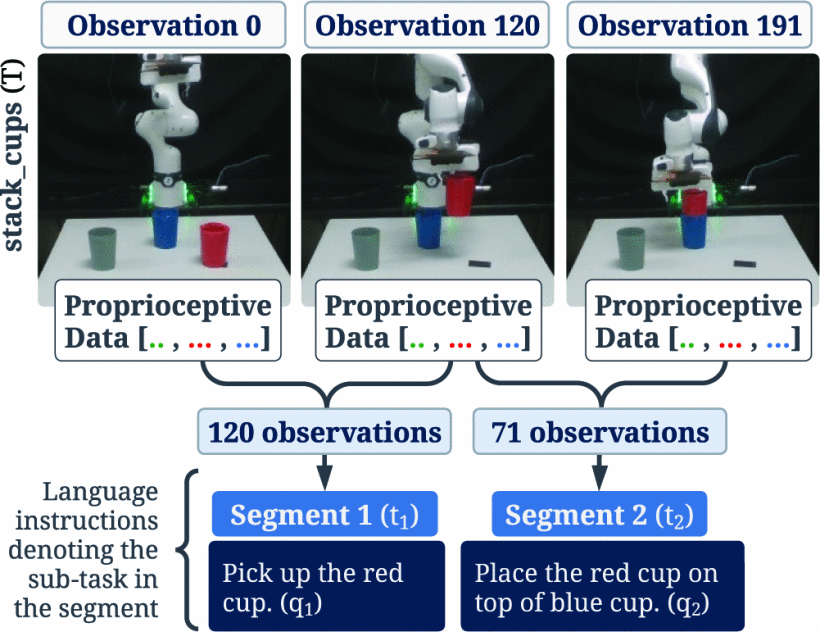
- IROS 2024 Compositional LearningLearning Temporally Composable Task Segmentations with LanguageTL;DR We present an approach to identify sub-tasks within a demonstrated robot trajectory with the supervision provided by language instructions.In 2024 IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS), Oct 2024
- IROS 2024 Robotics SystemsHardware-Software Co-Design for Path Planning by DronesTL;DR A hardware-software co-design, MT+, for adapting the Mikami-Tabuchi algorithm for on-board path planning by drones in a 3D environment.In 2024 IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS), Oct 2024
- arXiv 2024 Compositional Learning Policy AdaptationComposing Diffusion Policies for Few-shot Learning of Movement TrajectoriesTL;DR A compositional approach called DSE - Diffusion Score Equilibrium - that enables few-shot learning for novel skills by utilizing a combination of base policy priors.arXiv preprint arXiv:2410.17479, Oct 2024
- CVIP 2021Visual Localization Using Capsule NetworksTL;DR We achieved better results with capsules than with baseline-CNN PoseNet on small NORB dataset, modified for the task of camera pose estimation.In International Conference on Computer Vision and Image Processing, Oct 2021